Portainer and Authentik / Traefik failling to login due to UFW

Status: CURRENT — ENVIRONMENT-SPECIFIC FIX
Last reviewed: 31 August 2026
Applies to: Portainer + Authentik OAuth/OIDC behind Traefik with UFW enabled

This was the fix for my setup. If disabling UFW immediately makes the Authentik login work, the firewall path is involved. Docker and UFW interact in slightly weird ways though, so don’t assume every Docker host will behave exactly the same.

I use Authentik with Traefik for SSO, and Portainer authenticates against Authentik using OAuth/OIDC.

Authentik still has a Portainer integration guide, although that page still notes it was originally based on Authentik 2021.7.3 and Portainer 2.6.x. Portainer’s current documentation still supports a Custom OAuth provider.

This post isn’t another full Portainer/Authenik setup guide. It’s for the stupid problem I hit after the OAuth configuration looked correct.

The problem

When I tried logging into Portainer through Authentik, the login failed. Inspecting the browser console showed a request returning 404, which eventually resulted in a 401 Unauthorized.
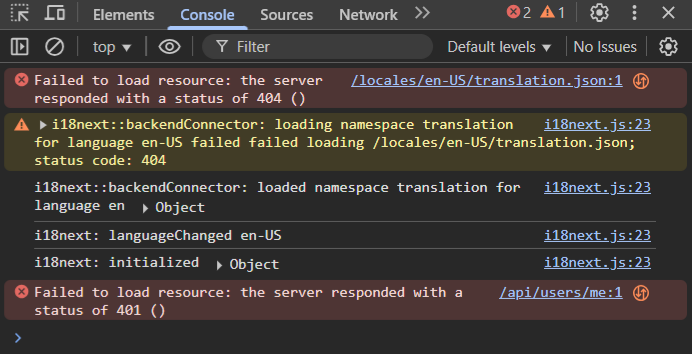
Portainer Authentik login failure
Browser console showing the authentication request error

Portainer, Authentik and Traefik were already on the expected Docker networks and changing the Traefik configuration wasn’t getting me anywhere.

The thing that finally exposed the problem was testing with UFW disabled.

Check UFW first

Before changing anything, check the current firewall state:

sudo ufw status verbose


If Traefik is supposed to be reachable over HTTPS but there is no rule allowing the traffic you expect, that is worth investigating before ripping apart your Authentik configuration.

Temporarily disable UFW as a test

Diagnostic test only: disabling the firewall removes protection from the host while it is off. Don’t leave UFW disabled as the fix.

Temporarily disable UFW:

sudo ufw disable


Now try the Portainer → Authentik login again.

In my case it immediately worked. That told me the OAuth configuration itself wasn’t the problem — traffic involved in the HTTPS authentication flow was being blocked by my firewall setup.

Why being on the same Docker network didn’t save it

This caught me out because Portainer, Authentik and Traefik were on Docker networks together.

OAuth/OIDC isn’t necessarily just container-to-container traffic. Your browser is redirected between the Portainer and Authentik HTTPS URLs, and the callback returns through those hostnames. If the HTTPS path to Traefik is broken, the authentication flow can fail even though the containers themselves can communicate internally.

Docker + UFW warning: Docker’s normal published ports are implemented with Docker-managed firewall/NAT rules, and Docker documents that published container ports can bypass the normal UFW INPUT/OUTPUT rules.

Because of that, ufw allow 443 is not universally required for every Docker-published Traefik instance. If toggling UFW changes the result on your host, inspect how Traefik exposes 80/443 and any custom forwarding/firewall rules rather than assuming this exact fix applies everywhere.

Check how Traefik is listening

A quick check on the Docker host:

sudo ss -lntp | grep -E ':(80|443)\b'


You can also check Docker’s published ports:

docker ps --format 'table {{.Names}}\t{{.Ports}}'


This helps work out whether Traefik is listening directly on the host, using Docker port publishing, host networking, or something more customised.

The fix on my host

Once I confirmed UFW was involved, I re-enabled it and allowed HTTP/HTTPS for Traefik.

If you’re connected to the server remotely over SSH, make sure SSH is already allowed before enabling UFW or you can lock yourself out.

sudo ufw allow OpenSSH
sudo ufw allow 80/tcp comment 'Allow HTTP for Traefik'
sudo ufw allow 443/tcp comment 'Allow HTTPS for Traefik'
sudo ufw enable
sudo ufw reload


Then confirm the rules:

sudo ufw status numbered


After that, the Portainer login through Authentik worked normally again.

Do you actually need port 80?

Not necessarily. If your Traefik setup only needs HTTPS and you aren’t using port 80 for an HTTP → HTTPS redirect or an ACME HTTP challenge, then you may only need:

sudo ufw allow 443/tcp comment 'Allow HTTPS for Traefik'


Open only what your setup actually needs.

If disabling UFW does NOT fix it

Then stop blaming UFW 😅 and go back through the OAuth flow.

  • Confirm the Portainer redirect URL exactly matches the redirect URI configured in Authentik.
  • Confirm Portainer’s Authorization, Access Token and Resource/UserInfo URLs point at the correct Authentik instance.
  • Check the Client ID and Client Secret.
  • Portainer’s OAuth scopes should be space-separated, not comma-separated.
  • Confirm both the Portainer and Authentik hostnames are reachable from the browser performing the login.
  • Check Traefik and Authentik logs while reproducing the login.

Portainer’s current documentation still supports Settings → Authentication → OAuth → Custom, so the general Authentik-as-OIDC-provider design remains valid.

Summary

For me, the giveaway was simple:

UFW enabled  → Authentik login fails
UFW disabled → Authentik login works


That narrowed the problem from “something is broken in Authentik/Portainer/Traefik” to “the firewall path is involved”, which was a hell of a lot easier to troubleshoot.

Just remember that Docker’s own firewall rules can bypass UFW for normally published container ports, so treat this as a troubleshooting method and my specific fix rather than a universal Docker rule.

References

Jellyfin and Authentik OIDC with admin

Status: CURRENT — COMMUNITY OIDC / PRE-STABLE PLUGIN
Last reviewed: 31 August 2026
Applies to: Jellyfin + Authentik using the community SSO/OIDC plugin

Important: Authentik’s current official Jellyfin integration guide now recommends LDAP, not OIDC. This article is specifically for people who still want OIDC/SSO through the community Jellyfin SSO plugin.

⚠️ Keep a break-glass Jellyfin admin account. A bad role mapping can remove administrator permissions from the account you normally use. Before changing SSO/admin-role settings, create or keep a second local Jellyfin administrator that does not depend on OIDC.

A quick 2026 update

When I originally wrote this article, the common OIDC option was the 9p4/jellyfin-plugin-sso plugin. That repository was archived by its author on 12 May 2026.

There is now a community revival maintained under Flowfin/jellyfin-plugin-sso. It supports Authentik over OpenID Connect and retains role-based mappings including administrator roles. It also keeps the same plugin GUID as the original 9p4 plugin, so it is designed to install over an existing installation while keeping the configuration.

At the time of this review the Flowfin project is still pre-stable/release-candidate software, so read its current installation notes before using it on a production Jellyfin server.

If you just want the Authentik-supported path with fewer moving parts, the current Authentik Jellyfin guide uses Jellyfin’s LDAP Authentication plugin instead.

The admin-role problem

With the OIDC SSO plugin, Jellyfin can use a role/group claim from Authentik to decide whether an SSO user should have Jellyfin administrator permissions.

The important settings are:

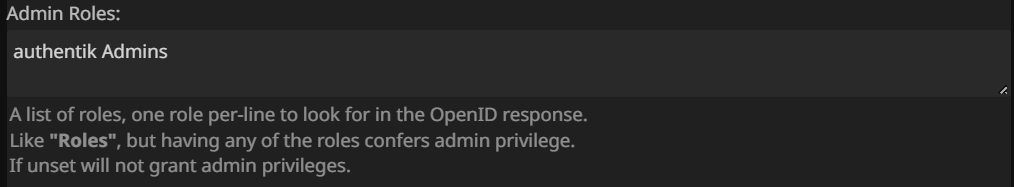
  • Role Claim: usually groups when using Authentik’s group claim.
  • Admin Roles: the exact Authentik group name that should grant Jellyfin administrator access.

For example, I originally used Authentik’s default administrator group:

authentik Admins


You can also create a dedicated group specifically for Jellyfin administrators, which is cleaner than tying Jellyfin permissions to Authentik’s own superuser/admin group.

In Authentik go to:

Admin Interface → Directory → Groups → Create


Create something like:

jellyfin-admins


Add only the users who should have Jellyfin administrator access to that group, then configure the Jellyfin SSO plugin with:

Role Claim: groups
Admin Roles: jellyfin-admins


The group name needs to match the value Authentik actually sends in the groups claim.

Jellyfin SSO plugin Admin Roles and Role Claim configuration

I also resized this screenshot from the original article because WordPress was rendering the full-size image way too large and making it look stretched.

Why admin access can disappear

The SSO plugin uses the role/group information supplied by the identity provider to determine administrator status. If your configured Admin Roles do not match anything in the incoming role claim, the SSO login may no longer receive Jellyfin administrator permissions.

This is why I strongly recommend keeping a separate local admin account while testing SSO. Don’t make your only Jellyfin administrator depend on an external identity provider and a role mapping you’re still configuring.

Fixing an existing locked-out admin

Credit to Spyros from the comments for this recovery method.

If you’ve already configured OIDC and your normal Jellyfin account has lost administrator access, the plugin configuration can be edited directly.

On my Docker setup the configuration was under:

/jellyfin/data/plugins/configurations/SSO-Auth.xml


Your actual host path may differ depending on where the Jellyfin /config volume is mounted. The important part is the Jellyfin plugin configuration file:

plugins/configurations/SSO-Auth.xml


Find the <AdminRoles> section and make sure it contains the exact Authentik group that should grant administrator access.

<AdminRoles>
  <string>authentik Admins</string>
</AdminRoles>


Or, if you’ve created a dedicated Jellyfin administrator group:

<AdminRoles>
  <string>jellyfin-admins</string>
</AdminRoles>


Save the file and restart Jellyfin.

After logging in again through Authentik, the account should regain Jellyfin administrator rights as long as the configured group is present in the incoming role claim.

If it still doesn’t work

Don’t just keep changing AdminRoles randomly. First confirm what Authentik is actually sending.

  • Confirm the Jellyfin plugin’s Role Claim is set to the claim containing your groups — commonly groups with Authentik.
  • Confirm the exact Authentik group name matches the value entered in Admin Roles, including spaces and capitalisation.
  • Confirm the user is actually a member of that Authentik group.
  • Check the Jellyfin logs during an SSO login for role/claim errors.
  • Keep your local break-glass admin available until the SSO mapping has been tested successfully.

Official LDAP vs community OIDC

As of August 2026 there are effectively two Authentik/Jellyfin paths:

  • LDAP: the method currently documented by Authentik. It uses Authentik’s LDAP provider/outpost plus Jellyfin’s LDAP Authentication plugin.
  • OIDC: the community SSO-plugin method covered by this article. The old 9p4 project is archived; the Flowfin revival is the current continuation but is not yet a stable release.

I still prefer OIDC conceptually for browser SSO, so I’m keeping this article rather than archiving it completely. Just be aware that it is now a community-plugin path, not Authentik’s current official Jellyfin integration.

References

And seriously — keep that second local admin until you’ve proved the OIDC role mapping works. Saving five minutes during setup isn’t worth locking yourself out of your own Jellyfin server 😅

Proxmox cluster with Traefik

Status: CURRENT
Last reviewed: 31 August 2026
Applies to: Proxmox VE 8/9 cluster + Traefik v3.x

Traefik can sit in front of multiple Proxmox nodes so a single hostname such as proxmox.richay.au reaches whichever cluster node is available. Modern Traefik supports Proxmox shell/noVNC WebSockets without a special WebSocket middleware.

Why put a Proxmox cluster behind Traefik?

Each node in a Proxmox cluster provides the web interface, and Proxmox cluster management can be performed by connecting to any cluster node.

Instead of remembering:

https://10.10.10.1:8006
https://10.10.10.2:8006
https://10.10.10.3:8006


I can use one address:

https://proxmox.richay.au


Traefik then load balances the browser traffic between the available nodes.

Security: Proxmox is a management interface with control over your VMs, containers, storage and cluster. I recommend keeping this hostname private rather than publishing it to the open internet.

I use Tailscale Split DNS for this type of service so proxmox.richay.au resolves only while I’m at home or connected to Tailscale. My guide is here: Tailscale Split DNS by Domain for Secure Home Server Access.

The old WebSocket workaround is no longer needed

The original version of this article added these request headers manually:

Upgrade: websocket
Connection: Upgrade


That is no longer required with current Traefik. Traefik v3 supports WebSocket and WebSocket Secure connections out of the box and automatically handles the protocol upgrade using normal HTTP routing.

So there is no need for a custom websocket-upgrade middleware just to make the Proxmox shell or noVNC console work.

Current Traefik dynamic configuration

This is the modern equivalent of my original config.yaml.

This example assumes your Proxmox nodes are using their normal cluster-generated HTTPS certificates and Traefik is connecting to them by IP address. Because those certificates are normally signed by the private Proxmox cluster CA, the example uses a dedicated ServersTransport with certificate verification disabled.

http:
  routers:
    proxmox:
      entryPoints:
        - "https"
      rule: "Host(`proxmox.richay.au`)"
      service: proxmox
      tls: {}

  services:
    proxmox:
      loadBalancer:
        serversTransport: proxmox-transport

        sticky:
          cookie:
            name: proxmox_lb
            secure: true
            httpOnly: true
            sameSite: lax

        servers:
          - url: "https://10.10.10.1:8006" # Proxmox node 1
          - url: "https://10.10.10.2:8006" # Proxmox node 2
          - url: "https://10.10.10.3:8006" # Proxmox node 3

  serversTransports:
    proxmox-transport:
      insecureSkipVerify: true


That’s it. No manual WebSocket headers.

Why use a sticky cookie?

Traefik’s load balancer normally distributes requests between the backend servers. Enabling a sticky cookie keeps subsequent requests from the same browser session on the same Proxmox node where possible.

For a normal website that may not matter much, but for a management UI with long-running shell/noVNC connections I prefer keeping the browser pinned to one node during the session.

The example also marks Traefik’s affinity cookie as Secure and HTTPOnly.

About insecureSkipVerify

insecureSkipVerify: true does not disable HTTPS. Traffic between Traefik and Proxmox is still encrypted, but Traefik does not verify that the backend certificate is trusted and belongs to the expected server.

That’s convenient for a trusted home management network, but it is weaker than actually trusting the Proxmox cluster CA.

Proxmox creates its own cluster CA by default and generates a node certificate for each node. The public cluster CA is stored at:

/etc/pve/pve-root-ca.pem


If you want proper backend certificate verification, copy only the public CA certificate to the Traefik host/container and use node hostnames that match the certificates.

For example:

http:
  services:
    proxmox:
      loadBalancer:
        serversTransport: proxmox-trusted
        sticky:
          cookie:
            name: proxmox_lb
            secure: true
            httpOnly: true

        # Use the actual DNS names present in your node certificates.
        servers:
          - url: "https://pve1.home.arpa:8006"
          - url: "https://pve2.home.arpa:8006"
          - url: "https://pve3.home.arpa:8006"

  serversTransports:
    proxmox-trusted:
      rootCAs:
        - /etc/traefik/certs/pve-root-ca.pem


This is the better option if you want end-to-end TLS verification rather than simply trusting the management LAN.

Do not copy the Proxmox cluster CA private key to Traefik. The public pve-root-ca.pem certificate is all Traefik needs to trust the cluster certificates.

HTTPS redirect

My old dynamic configuration attached an HTTPS redirect middleware to the router even though that router was already listening on the HTTPS entrypoint. That’s redundant.

If you want every request hitting port 80 to redirect to HTTPS, I prefer doing that once on the HTTP entrypoint in Traefik’s static/install configuration:

entryPoints:
  http:
    address: ":80"
    http:
      redirections:
        entryPoint:
          to: https
          scheme: https

  https:
    address: ":443" 


Then every service can use the HTTPS entrypoint without carrying around its own redirect middleware.

Testing it

Open the single cluster hostname:

https://proxmox.richay.au


Log into Proxmox and test:

  • Normal cluster navigation.
  • A node shell.
  • An LXC console.
  • A VM noVNC console.

They should work through the same Traefik route without any WebSocket-specific middleware.

If the normal web UI loads but consoles fail, check the browser developer tools for the WebSocket request and check the Traefik logs. Don’t immediately add fake Upgrade headers back in — modern Traefik already handles that part.

What happens when a node goes down?

Traefik can distribute requests across multiple Proxmox nodes, but this alone is not a full HA design. If the node your sticky cookie points to disappears, Traefik can select another backend when the failed backend is detected, but an existing shell/noVNC connection to the dead node will obviously be lost.

The reverse proxy gives you one convenient cluster URL. Proxmox clustering/HA is still what handles the actual guests and cluster state.

Archived note from the original article

ARCHIVED — old Traefik WebSocket middleware

The original article used a websocket-upgrade Headers middleware with Upgrade: websocket and Connection: Upgrade. That workaround has been removed from the active configuration because current Traefik handles WebSocket upgrades automatically.

References

Much cleaner now — one cluster URL, sticky sessions, working shells, and no janky WebSocket header hack required 🙂

Authentik and Home Assistant with working Companion App solution using Traefik proxy

Status: CURRENT — MAJOR 2026 UPDATE
Last reviewed: 31 August 2026
Applies to: Home Assistant, Authentik and Traefik with the Home Assistant Companion App

The original two-hostname workaround in this article still explains a real problem, but the component it relied on has now been archived. In 2026 I recommend authenticating Home Assistant directly with Authentik over OIDC instead of putting Authentik Forward Auth in front of Home Assistant.

I absolutely love logging into Authentik once and getting SSO across the homelab. Home Assistant used to be one of the awkward exceptions.

The original version of this article solved that by creating two Traefik routes:

  • A browser hostname protected by Authentik Forward Auth, using hass-auth-header to log the user into Home Assistant.
  • A second hostname that bypassed Authentik and showed Home Assistant’s normal login page so the Companion App could authenticate.

That workaround worked, and judging by the traffic/comments it helped quite a few people. But the Home Assistant authentication landscape has changed enough that I wouldn’t build a fresh setup that way now.

What changed?

The BeryJu/hass-auth-header component used by the original guide was archived on 23 October 2025. Its maintainer specifically points users toward newer Home Assistant OIDC integrations instead.

A maintained community project called OpenID Connect for Home Assistant now lets Home Assistant itself authenticate against Authentik using standard OIDC.

That means Authentik no longer needs to sit in front of Home Assistant as a Forward Auth middleware. Traefik just proxies Home Assistant normally, and Home Assistant performs the Authentik login itself.

Why this is better for the Companion App: the maintained OIDC integration is designed to handle Home Assistant login in both the web interface and Companion App. Its maintainer specifically advises removing reverse-proxy-level authentication when migrating from header-auth setups, because an extra authentication layer in front of Home Assistant can interfere with the app’s login flow.

Recommended 2026 setup

The new layout is much simpler:

Browser / Companion App
          ↓
https://home-assistant.richay.au
          ↓
       Traefik
          ↓
   Home Assistant
          ↓
 Authentik via OIDC


There is only one Home Assistant hostname, and there is no Authentik Forward Auth middleware in front of it.

1. Keep Traefik as a normal reverse proxy

Current Traefik does not need any special configuration for Home Assistant’s WebSocket traffic. A normal HTTPS router is enough.

Home Assistant changed its HTTP defaults in 2026.8:

  • Home Assistant OS: new default HTTP server port is 80.
  • Home Assistant Container: default remains 8123.
  • If you’ve manually configured another port, use whatever is shown under Settings → System → Network → HTTP server.

For a current Home Assistant OS install using port 80, my Traefik dynamic config would look roughly like this:

http:
  routers:
    home-assistant:
      entryPoints:
        - "https"
      rule: "Host(`home-assistant.richay.au`)"
      tls: {}
      service: home-assistant

  services:
    home-assistant:
      loadBalancer:
        servers:
          - url: "http://10.10.10.10:80" # Home Assistant OS 2026.8+ default


If you’re running Home Assistant Container, or your HAOS instance still uses the old/custom port, change the backend to:

url: "http://10.10.10.10:8123"


There is deliberately no Authentik middleware on this router. OIDC happens inside Home Assistant.

2. Configure Home Assistant to trust Traefik

Another 2026 change: from Home Assistant 2026.8, the HTTP server/reverse-proxy settings moved out of configuration.yaml and into the UI.

Go to:

Settings → System → Network → HTTP server


Enable Trust X-Forwarded-For and add Traefik under Trusted proxies.

If Traefik reaches Home Assistant from a Docker network such as 172.22.0.0/16, that is the network you would trust.

Don’t blindly trust your entire home LAN. The old version of this article included the whole 10.10.10.0/24 home network as a trusted proxy. Home Assistant’s setting is specifically for reverse proxies that are allowed to supply X-Forwarded-For. Trust only the Traefik IP/network that actually proxies the request.

If you’re still running a Home Assistant release before 2026.8, the equivalent old YAML was:

http:
  use_x_forwarded_for: true
  trusted_proxies:
    - 172.22.0.0/16 # Replace with your Traefik proxy network


3. Install the Home Assistant OIDC integration

Install OpenID Connect for Home Assistant through HACS.

After installing and restarting Home Assistant, go to:

Settings → Devices & Services → Add Integration → OpenID Connect/SSO Authentication


The integration includes an Authentik-specific setup flow.

4. Create the Authentik OIDC application

In Authentik, create an Application with an OAuth2/OpenID Connect Provider.

The current integration guide recommends a Strict redirect URI of:

https://home-assistant.richay.au/auth/oidc/callback


Select an Authentik signing key so the provider uses signed ID tokens. The current Authentik setup guide for this integration uses an RS256 signing key.

Make note of the:

  • Client ID
  • Client Secret, if you’re using a confidential client
  • Application/provider slug

The OIDC discovery URL will look like:

https://auth.example.com/application/o/home-assistant/.well-known/openid-configuration


Replace the Authentik hostname and provider slug with your own.

5. Configure Home Assistant

In the Home Assistant OIDC integration:

  1. Select Authentik.
  2. Enter the Authentik discovery URL.
  3. Enter the Client ID and Client Secret if required.
  4. Configure user/group/role mapping as needed.
  5. Test SSO before removing or disabling any local login method.

Keep a local break-glass Home Assistant admin. Don’t make an external identity provider your only way back into the system until you’ve tested browser and Companion App login properly.

6. Use the same URL in the Companion App

The Companion App can now use the same address as the browser:

https://home-assistant.richay.au


There should no longer be a need for a second home-companion.* hostname just to bypass Authentik, because Authentik is no longer authenticating at the reverse-proxy layer.

Keeping Home Assistant private with Tailscale

You don’t have to publish the Home Assistant hostname to the open internet.

Home Assistant’s own current remote-access documentation lists VPN access such as Tailscale as a secure option. If your phone stays connected to Tailscale, the Companion App can continue updating sensors and reaching Home Assistant through the VPN.

I use Split DNS for this type of setup so the nice *.richay.au names resolve to my internal reverse proxy only while I’m at home or connected to Tailscale.

My guide is here: Tailscale Split DNS by Domain for Secure Home Server Access.

Legacy method — the original two-hostname workaround

LEGACY / NOT RECOMMENDED FOR NEW INSTALLS

I’m keeping this section because this article was widely used and existing installations may still be running it. The method relies on the now-archived hass-auth-header custom component.

The original workaround looked like this:

Browser
  ↓
home-assistant.example.com
  ↓
Traefik + Authentik Forward Auth
  ↓
X-authentik-username
  ↓
hass-auth-header
  ↓
Home Assistant

Companion App
  ↓
home-companion.example.com
  ↓
Traefik WITHOUT Authentik
  ↓
Normal Home Assistant login


That architecture solved the Companion App problem because the app never had to pass through Authentik Forward Auth.

However, the second hostname is not magically secure. If home-companion.example.com is publicly reachable, anyone can reach Home Assistant’s normal login screen through it. Making the hostname obscure is not meaningful protection.

If you continue using this old method, make the Companion hostname private using LAN DNS, Tailscale Split DNS, a VPN, firewall rules, or another real access-control boundary.

Legacy hass-auth-header configuration

The custom component itself still expected something similar to:

auth_header:
  username_header: X-authentik-username


Reverse-proxy trust is separate. On current Home Assistant releases configure Traefik under Settings → System → Network → HTTP server rather than adding a new http: YAML block.

The archived hass-auth-header project itself warns that a bad configuration can allow unintended access to Home Assistant. If you keep using it, only trust headers arriving from your actual reverse proxy and plan a migration to OIDC.

Why Authentik Forward Auth can still break the Companion App

This part of the original article remains relevant.

Reverse proxying Home Assistant is fine. The problem is adding a separate authentication wall in front of Home Assistant.

The current Home Assistant OIDC integration’s maintainer explicitly describes reverse proxy + proxy-level authentication as an unsupported scenario for the Companion App. When the login flow leaves the Home Assistant domain for an extra proxy authentication step, the app can fail to complete its own authorization hand-off.

That’s why the modern solution is:

Traefik: reverse proxy only
Home Assistant: handles authentication
Authentik: OIDC identity provider


rather than:

Traefik: reverse proxy + authentication gate
Home Assistant: receives pre-authenticated headers


Troubleshooting

If the browser works but the Companion App does not:

  • Make sure you are not still applying an Authentik Forward Auth middleware to the Home Assistant router.
  • Make sure the app is using the same Home Assistant hostname configured in the Authentik redirect URI.
  • Confirm Home Assistant trusts Traefik as a reverse proxy.
  • Confirm the OIDC callback is exactly /auth/oidc/callback.
  • Test local Home Assistant login as a fallback before assuming the issue is OIDC.
  • Check Home Assistant logs and Authentik provider/outpost logs during the login attempt.

If Home Assistant returns 400 Bad Request behind Traefik, check the HTTP Server settings and confirm the Traefik IP/network is listed under Trusted proxies.

References

The old workaround did its job, but this is one of those rare cases where the newer method is actually simpler: one hostname, proper OIDC, no header-auth hack, and the Companion App doesn’t need its own secret back door 🙂

Ansible – updating proxmox host kernel with LXC shared GPU

Status: ARCHIVED — HISTORICAL NVIDIA WORKAROUND
Last reviewed: 31 August 2026
Originally applied to: Proxmox + shared NVIDIA GPU into LXC using manually installed NVIDIA drivers

Do not copy the old playbook as a current NVIDIA update procedure. It hard-codes an old NVIDIA driver and treats manual driver reinstallation after a kernel update as normal. With a properly configured DKMS installation, the NVIDIA kernel module should normally rebuild for the new kernel automatically.

Is this still relevant?

Mostly no. I’m keeping the page because the problem it was trying to solve still exists, but the automation itself belongs to an older version of my setup.

The original idea was simple: after upgrading the Proxmox kernel, check whether the NVIDIA module loaded. If it didn’t, reinstall the NVIDIA .run driver on the host, reboot, then reinstall the matching NVIDIA userspace driver inside the Plex LXC.

The old playbook was built around a fixed NVIDIA driver:

NVIDIA-Linux-x86_64-535.154.05.run


That’s the first reason not to use it today. More importantly, a kernel update by itself should not normally require reinstalling the whole NVIDIA driver.

What should happen now?

For an NVIDIA driver installed with DKMS:

  1. A new Proxmox kernel is installed.
  2. The matching Proxmox kernel headers are available.
  3. DKMS builds the NVIDIA kernel module for that new kernel.
  4. You reboot into the new kernel.
  5. nvidia-smi continues to work.

NVIDIA’s current documentation says that kernel updates can occasionally leave DKMS without the correct headers or fail to rebuild the module. When that happens, the modern fix is normally to diagnose/rebuild DKMS rather than blindly reinstalling an old driver package.

Useful checks after a Proxmox kernel update

uname -r
nvidia-smi
dkms status


Make sure the headers for the running kernel are installed:

apt update
apt install proxmox-headers-$(uname -r)


Depending on the driver installation method and package naming, you can then rebuild the NVIDIA DKMS module rather than reinstalling the entire driver.

Proxmox 9 note: NVIDIA kernel/module compatibility can still genuinely break on newer Proxmox kernels. There have been current Proxmox 9.2 reports involving kernel 7.x, DKMS build failures and conflicts with newer kernel drivers. So if nvidia-smi dies after an upgrade, don’t assume your LXC passthrough configuration is the problem — check the host NVIDIA module first.

What about the LXC?

For shared NVIDIA GPU access, the LXC uses the NVIDIA kernel driver loaded by the Proxmox host. The container does not build its own kernel module.

The old playbook installed the same NVIDIA package inside the LXC using:

./NVIDIA-Linux-x86_64-535.154.05.run --no-kernel-module


That installs the userspace side without attempting to build a kernel module inside the container.

The important distinction is that a kernel update does not automatically mean those userspace libraries changed. You normally only need to revisit the LXC-side NVIDIA libraries when the actual NVIDIA driver version changes or the userspace/kernel versions no longer match.

Proxmox device passthrough is cleaner now too

Current Proxmox supports native LXC device passthrough using dev[n] entries, including configurable path, UID, GID and mode. That has replaced a lot of the older hand-written cgroup/bind-mount hacks used in historical GPU-sharing guides.

The NVIDIA-specific wrinkle remains: the host still needs a functioning NVIDIA kernel driver before any /dev/nvidia* devices can be shared into the LXC.

If I automated this today

I would automate verification, not automatic driver reinstallation.

For example, an Ansible playbook can check the host after updates and deliberately fail if the NVIDIA stack is broken:

- name: Verify NVIDIA after Proxmox update
  hosts: proxmox
  become: true

  tasks:
    - name: Check running kernel
      ansible.builtin.command: uname -r
      register: running_kernel
      changed_when: false

    - name: Check NVIDIA
      ansible.builtin.command: nvidia-smi
      register: nvidia_smi
      changed_when: false
      failed_when: false

    - name: Check DKMS state
      ansible.builtin.command: dkms status
      register: dkms_status
      changed_when: false
      failed_when: false

    - name: Stop if NVIDIA is broken
      ansible.builtin.fail:
        msg: |
          NVIDIA did not initialise after the kernel update.
          Kernel: {{ running_kernel.stdout }}
          nvidia-smi:
          {{ nvidia_smi.stdout }}
          {{ nvidia_smi.stderr }}

          DKMS:
          {{ dkms_status.stdout }}
      when: nvidia_smi.rc != 0


That gives you the automation benefit without having Ansible silently run an obsolete .run installer against whatever kernel happened to arrive that day.

Original playbook — archived for reference

ARCHIVED CODE — DO NOT USE AS-IS. This is the original playbook from this article. It is preserved so old links and search results still make sense, not because I recommend deploying it in 2026.

########
- hosts: nvidia
  become: true
  become_user: root
  tasks:
    - name: Wait for 10.77.69.2 to become available
      wait_for_connection:
        delay: 5
        timeout: 300

    - name: Check if NVIDIA kernel module is loaded
      shell: lsmod | grep -q '^nvidia'
      register: nvidia_module_check
      ignore_errors: true

    - name: Set NVIDIA module check result as fact
      set_fact:
        nvidia_module_rc: "{{ nvidia_module_check.rc }}"

    - name: Reinstall NVIDIA driver if module is not loaded
      shell: sh /root/NVIDIA-Linux-x86_64-535.154.05.run --silent
      args:
        executable: /bin/bash
      when: nvidia_module_check.rc != 0

    - name: Set fact if NVIDIA driver was installed
      set_fact:
        driver_installed: true
      when: nvidia_module_check.rc != 0

    - name: Reboot system if NVIDIA driver was reinstalled
      reboot:
      when: nvidia_module_check.rc != 0

    - name: Wait for 10.77.69.2 to become available after reboot
      wait_for_connection:
        delay: 10
        timeout: 600
      when: nvidia_module_check.rc != 0

########
- hosts: plex
  become: true
  become_user: root
  tasks:
    - name: Install NVIDIA driver in LXC
      shell: sh /root/NVIDIA-Linux-x86_64-535.154.05.run --no-kernel-module --silent
      args:
        executable: /bin/bash
      when: hostvars['10.77.69.2'].driver_installed | default(false)

    - name: Reboot 10.77.69.103
      reboot:
      when: hostvars['10.77.69.2'].driver_installed | default(false)

    - name: Wait for 10.77.69.103 to become available
      wait_for_connection:
        delay: 10
        timeout: 300
      when: hostvars['10.77.69.2'].driver_installed | default(false)


Why I’m archiving it instead of deleting it

The original problem was real and NVIDIA + new Proxmox kernels can still occasionally go cactus. But the correct troubleshooting path has changed.

Today I’d check:

  • Is the running Proxmox kernel supported by the installed NVIDIA driver?
  • Are the matching Proxmox kernel headers installed?
  • Did DKMS actually build/install the NVIDIA module for the running kernel?
  • Does nvidia-smi work on the host?
  • Do the /dev/nvidia* devices exist?
  • Only then: does the LXC have the right devices and compatible NVIDIA userspace libraries?

That’s a better model than treating every kernel update as “reinstall NVIDIA everywhere and reboot twice”.

References

Nvidia GPU passthrough in LXC

Status: CURRENT — MAJOR 2026 UPDATE
Last reviewed: 31 August 2026
Applies to: Proxmox VE 8.2+/9.x, NVIDIA GPU device sharing into LXC containers

The idea behind this article is still useful, but the old configuration method is not. Current Proxmox has native LXC Device Passthrough, so you no longer need to hand-write cgroup rules and bind mounts for every NVIDIA device.

Credit where it’s due: the original version of this guide was based on TheOrangeOne’s NVIDIA LXC GPU passthrough article. That method got me working at the time, but Proxmox has made this a hell of a lot cleaner since then.

First: this is not PCIe passthrough

With normal PCIe passthrough you hand the physical GPU over to one VM. The host effectively lets go of it.

This setup is different. The NVIDIA driver stays loaded on the Proxmox host, and the host’s NVIDIA device nodes are exposed to an LXC.

That means the same physical NVIDIA GPU can potentially be exposed to multiple containers at the same time.

Think of it as sharing access to the host GPU driver, not giving the entire PCIe device away.

The old guide is very old now 🙂

The original article used a GTX 760 with NVIDIA driver 450.80.02, manually downloaded the NVIDIA .run installer, created device nodes with custom udev rules, then edited the LXC config with lxc.cgroup2.devices.allow and lxc.mount.entry.

All of that made sense at the time. Most of it is now either unnecessary or something I’d avoid on a fresh build.

Jellyfin users: Jellyfin 10.11 currently requires NVIDIA driver 520.56.06 or newer. NVIDIA’s Kepler GPUs are limited to the 470 legacy driver branch, so the old GTX 760 example from this article no longer meets Jellyfin’s current driver requirement. The poor little thing has finally earned retirement 😅.

1. Install a working NVIDIA driver on the Proxmox host

The host still needs the real NVIDIA kernel driver. That part has not changed.

Before installing the driver, make sure DKMS and the headers for the running Proxmox kernel are available:

apt update
apt install dkms proxmox-headers-$(uname -r)


Then install a current NVIDIA driver that supports your GPU and kernel using the current Debian/NVIDIA package instructions.

I no longer recommend hard-coding an ancient direct download such as:

NVIDIA-Linux-x86_64-450.80.02.run


Package-managed drivers with DKMS are much easier to keep working across Proxmox kernel updates. If you deliberately use NVIDIA’s .run installer, make sure DKMS is enabled so the module can rebuild for new kernels.

Reboot if required, then verify the host first:

uname -r
nvidia-smi
dkms status


If nvidia-smi is cactus on the Proxmox host, stop here. The LXC isn’t going to magically fix it.

2. Check which NVIDIA device nodes exist

On the Proxmox host:

ls -l /dev/nvidia* /dev/nvidia-caps/* 2>/dev/null


A typical modern NVIDIA setup may contain some or all of:

  • /dev/nvidia0
  • /dev/nvidiactl
  • /dev/nvidia-uvm
  • /dev/nvidia-uvm-tools
  • /dev/nvidia-modeset
  • /dev/nvidia-caps/nvidia-cap1
  • /dev/nvidia-caps/nvidia-cap2

Don’t copy a list from a random guide and assume your machine has exactly the same devices. NVIDIA driver versions, GPU generations and workloads can differ.

The old guide also assumed fixed character-device major numbers such as 195 and 243. We don’t need to care about that anymore. Yewww.

3. Pass the NVIDIA devices into the LXC

Proxmox VE introduced native container device passthrough in 8.1, and from 8.2 you can configure it directly in the web interface.

Stop the LXC, then go to:

LXC → Resources → Add → Device Passthrough


Add the NVIDIA device nodes that exist on your host.

For a simple media-server setup I normally start with the common device set below. Replace 103 with your container ID and skip any device that doesn’t exist on your host:

pct set 103 --dev0 path=/dev/nvidia0,mode=0666
pct set 103 --dev1 path=/dev/nvidiactl,mode=0666
pct set 103 --dev2 path=/dev/nvidia-uvm,mode=0666
pct set 103 --dev3 path=/dev/nvidia-uvm-tools,mode=0666
pct set 103 --dev4 path=/dev/nvidia-modeset,mode=0666


If your workload needs the NVIDIA capability devices and they exist on your host, add them too:

pct set 103 --dev5 path=/dev/nvidia-caps/nvidia-cap1,mode=0666
pct set 103 --dev6 path=/dev/nvidia-caps/nvidia-cap2,mode=0666


About mode=0666: I’m using it here because it is the least painful way to prove the GPU works inside an unprivileged LXC. Proxmox creates the device node for the container with that access mode; you are not running a blanket chmod 666 /dev/nvidia* across the host.

Once everything works, you can tighten this using the uid, gid and mode options supported by Proxmox Device Passthrough.

Check what Proxmox saved:

pct config 103 | grep '^dev'


You should see entries similar to:

dev0: /dev/nvidia0,mode=0666
dev1: /dev/nvidiactl,mode=0666
dev2: /dev/nvidia-uvm,mode=0666
dev3: /dev/nvidia-uvm-tools,mode=0666
dev4: /dev/nvidia-modeset,mode=0666


4. Start the LXC and check the devices

Start the container and enter it:

pct start 103
pct enter 103


Then check the device nodes from inside the LXC:

ls -l /dev/nvidia* /dev/nvidia-caps/* 2>/dev/null


If they are present, the Proxmox side of the passthrough is basically done.

5. Install NVIDIA userspace libraries inside the LXC

This is the NVIDIA-specific annoying bit that still exists.

The LXC uses the host’s NVIDIA kernel module. You do not build another NVIDIA kernel module inside the container.

However, applications inside the LXC still need NVIDIA userspace libraries such as NVML, NVDEC and NVENC.

The userspace NVIDIA components inside the LXC need to be compatible with the NVIDIA kernel driver on the host. NVIDIA itself documents driver/library version mismatch errors when the client libraries and loaded kernel module don’t match.

For a Debian-based Jellyfin LXC, Jellyfin’s current documentation calls for its FFmpeg package plus the NVIDIA decode/encode libraries:

apt update
apt install jellyfin-ffmpeg7 libnvcuvid1 libnvidia-encode1


You will also need the matching NVIDIA userspace/NVML utilities for your driver branch so that nvidia-smi is available inside the LXC. Exact package names and versions vary depending on whether you’re using Debian’s NVIDIA packages or NVIDIA’s own repository, so keep them aligned with the host driver branch.

If you deliberately still use NVIDIA’s .run installer, installing the exact same driver version inside the LXC without kernel modules remains possible:

sudo sh ./NVIDIA-Linux-x86_64-<VERSION>.run --no-kernel-modules


I consider that the fallback method now, not the first choice. Package management + DKMS on the host is far less likely to turn a routine Proxmox update into a Saturday-night troubleshooting adventure.

6. Test NVIDIA from inside the LXC

nvidia-smi


If that shows the GPU, driver information and no NVML error, you’re in business.

If you get:

Failed to initialize NVML: Driver/library version mismatch


compare the loaded host driver and the libraries installed inside the LXC. That’s usually version drift, not a Proxmox device-passthrough problem.

7. Actually test hardware acceleration

nvidia-smi proving the GPU exists is nice, but it doesn’t prove Jellyfin/Plex can actually use NVENC/NVDEC.

Start a forced transcode and watch the GPU:

watch -n 1 nvidia-smi


You should see the transcoder process appear and GPU/video-engine activity increase.

For Jellyfin, select NVIDIA NVENC in the transcoding settings and only enable codecs your GPU actually supports. Current Jellyfin documentation is the best source for the codec/support matrix because NVIDIA’s generations and encode-session limits keep changing.

Can I share the same GPU with multiple LXCs?

Yes — and this remains one of the nicest reasons to do LXC device sharing instead of PCIe passthrough.

Because the NVIDIA driver remains owned by the Proxmox host, you can expose the same /dev/nvidia* device nodes to more than one LXC.

Obviously they still share the same physical GPU resources, VRAM and hardware encoder limits. We haven’t invented free GPUs yet. Bloody disappointing.

What if my app runs in Docker inside the LXC?

Then you’ve added another layer to the onion 🙂

This guide gets the NVIDIA GPU from Proxmox → LXC. If Jellyfin/Plex is then running inside Docker within that LXC, Docker also needs access to the NVIDIA devices/userspace stack. NVIDIA Container Toolkit or explicit Docker device mappings may be required depending on the image and runtime.

Always get nvidia-smi working directly inside the LXC first. Only then troubleshoot Docker. Otherwise you’re trying to debug two layers at once and life is too short.

Old method — archived

ARCHIVED — PRE-PROXMOX 8.1 METHOD

The old guide manually allowed NVIDIA character-device major numbers through cgroups and bind-mounted each device into the container. This is preserved only so old search results and existing installations make sense.

The old container configuration looked roughly like this:

lxc.cgroup2.devices.allow: c 195:* rwm
lxc.cgroup2.devices.allow: c 243:* rwm

lxc.mount.entry: /dev/nvidia0 dev/nvidia0 none bind,optional,create=file
lxc.mount.entry: /dev/nvidiactl dev/nvidiactl none bind,optional,create=file
lxc.mount.entry: /dev/nvidia-uvm dev/nvidia-uvm none bind,optional,create=file
lxc.mount.entry: /dev/nvidia-modeset dev/nvidia-modeset none bind,optional,create=file
lxc.mount.entry: /dev/nvidia-uvm-tools dev/nvidia-uvm-tools none bind,optional,create=file


Current Proxmox Device Passthrough replaces both the manual cgroup permission rules and the bind mounts, including for unprivileged containers.

Old udev chmod hack — also archived

The original article also created a custom udev rule that ran nvidia-smi/nvidia-modprobe and then did a wildcard chmod 666 /dev/nvidia* on the host.

I wouldn’t do that by default now. Modern NVIDIA installations include nvidia-modprobe, whose job includes creating the /dev/nvidia* nodes when required, and Proxmox’s device passthrough can set the permissions of the container-side device node itself.

If the NVIDIA device nodes are missing on the host, diagnose the NVIDIA driver/module first rather than immediately masking it with a global permissions rule.

Quick troubleshooting order

  1. nvidia-smi works on the Proxmox host.
  2. The expected /dev/nvidia* nodes exist on the host.
  3. Those nodes are configured with Proxmox Device Passthrough.
  4. The device nodes appear inside the LXC.
  5. The LXC has compatible NVIDIA userspace libraries.
  6. nvidia-smi works inside the LXC.
  7. Only then test Jellyfin/Plex hardware transcoding.

Do it in that order and you know exactly which layer went cactus.

References

Much less black magic than the original version. The NVIDIA driver can still throw the occasional tantrum after a kernel update, obviously — it wouldn’t be NVIDIA on Linux otherwise 🙂

Docker Stack with ExpressVPN

Status: CURRENT — MAJOR 2026 UPDATE
Last reviewed: 31 August 2026
Applies to: Docker Compose, ExpressVPN, qBittorrent, Prowlarr, Sonarr, Radarr and Lidarr

The original idea is still solid: make selected containers share a VPN container’s network namespace so their traffic cannot casually wander out through your normal WAN connection. The old stack still mostly makes sense, but I’ve rebuilt the recommended version around Gluetun because it handles the firewall/killswitch and DNS side much more cleanly.

This article started life as a giant entertainment stack using polkaned/expressvpn, with qBittorrent and all the *arr containers set to:

network_mode: service:expressvpn


That Docker trick is still completely valid. Docker Compose still supports network_mode: service:<name>, which makes one service use another service’s network stack.

The result is basically:

qBittorrent ─┐
Prowlarr    ├── shares VPN network namespace ── ExpressVPN ── Internet
Sonarr      │
Radarr      │
Lidarr     ─┘


If the VPN container’s firewall is doing its job, those applications don’t get an independent route straight out through your home connection.

What was wrong with my old stack?

Nothing catastrophically wrong, but a few bits have aged.

  • polkaned/expressvpn is actually still maintained, so that part didn’t die. Nice.
  • The current polkaned documentation warns that containers sharing its network namespace need the VPN container’s DNS configuration copied/shared as well to avoid DNS leakage. My old Compose didn’t do that.
  • The old VPN container ran privileged: true. Gluetun can do the job with NET_ADMIN and /dev/net/tun instead.
  • LinuxServer now documents its images using lscr.io/linuxserver/....
  • The old qBittorrent variable UMASK_SET has been replaced by UMASK.
  • I was using the Prowlarr develop tag for no particularly good reason. Stable latest is the sensible default now.
  • The old stack had separate /tv, /movies and /downloads mounts. A single common /data mount makes hardlinks and atomic moves far less cactus.

Recommended 2026 method: Gluetun + ExpressVPN

Gluetun has native ExpressVPN support and can act as the network container for everything else. Its firewall stays active and effectively acts as the VPN killswitch.

One limitation: Gluetun connects to ExpressVPN using ExpressVPN’s manual OpenVPN credentials. ExpressVPN’s own Linux app can use newer protocols such as Lightway, but their manual configuration currently supports OpenVPN.

1. Get the ExpressVPN manual credentials

These are not your normal ExpressVPN account email/password.

In your ExpressVPN account go to the manual configuration area and grab the generated OpenVPN username and password.

I keep mine in an .env file next to the Compose file instead of hard-coding them into the stack:

EXPRESSVPN_USER=replace_me
EXPRESSVPN_PASSWORD=replace_me
EXPRESSVPN_COUNTRY=Australia

PUID=1000
PGID=1000
TZ=Australia/Perth


Then lock the file down:

chmod 600 .env


2. Folder layout

My current Docker layout is:

/home/richay/docker-compose/   # Compose files + small hand-managed config
/home/richay/docker/           # Persistent container data


For this stack:

mkdir -p /home/richay/docker-compose/media-vpn
mkdir -p /home/richay/docker/{gluetun,qbittorrent,prowlarr,sonarr,radarr,lidarr}
mkdir -p /mnt/media/{downloads,tv,movies,music}


Change /mnt/media to wherever your real media/download storage is mounted.

3. Current Compose stack

services:
  gluetun:
    image: qmcgaw/gluetun:latest
    container_name: gluetun
    cap_add:
      - NET_ADMIN
    devices:
      - /dev/net/tun:/dev/net/tun
    environment:
      - VPN_SERVICE_PROVIDER=expressvpn
      - VPN_TYPE=openvpn
      - OPENVPN_USER=${EXPRESSVPN_USER}
      - OPENVPN_PASSWORD=${EXPRESSVPN_PASSWORD}
      - SERVER_COUNTRIES=${EXPRESSVPN_COUNTRY:-Australia}
      - TZ=${TZ:-Australia/Perth}
    volumes:
      - /home/richay/docker/gluetun:/gluetun
    ports:
      - "8080:8080" # qBittorrent WebUI
      - "9696:9696" # Prowlarr
      - "8989:8989" # Sonarr
      - "7878:7878" # Radarr
      - "8686:8686" # Lidarr
    restart: unless-stopped

  qbittorrent:
    image: lscr.io/linuxserver/qbittorrent:latest
    container_name: qbittorrent
    network_mode: service:gluetun
    environment:
      - PUID=${PUID:-1000}
      - PGID=${PGID:-1000}
      - TZ=${TZ:-Australia/Perth}
      - WEBUI_PORT=8080
      - TORRENTING_PORT=6881
      - UMASK=022
    volumes:
      - /home/richay/docker/qbittorrent:/config
      - /mnt/media:/data
    depends_on:
      gluetun:
        condition: service_healthy
    restart: unless-stopped

  prowlarr:
    image: lscr.io/linuxserver/prowlarr:latest
    container_name: prowlarr
    network_mode: service:gluetun
    environment:
      - PUID=${PUID:-1000}
      - PGID=${PGID:-1000}
      - TZ=${TZ:-Australia/Perth}
    volumes:
      - /home/richay/docker/prowlarr:/config
    depends_on:
      gluetun:
        condition: service_healthy
    restart: unless-stopped

  sonarr:
    image: lscr.io/linuxserver/sonarr:latest
    container_name: sonarr
    network_mode: service:gluetun
    environment:
      - PUID=${PUID:-1000}
      - PGID=${PGID:-1000}
      - TZ=${TZ:-Australia/Perth}
    volumes:
      - /home/richay/docker/sonarr:/config
      - /mnt/media:/data
    depends_on:
      gluetun:
        condition: service_healthy
    restart: unless-stopped

  radarr:
    image: lscr.io/linuxserver/radarr:latest
    container_name: radarr
    network_mode: service:gluetun
    environment:
      - PUID=${PUID:-1000}
      - PGID=${PGID:-1000}
      - TZ=${TZ:-Australia/Perth}
    volumes:
      - /home/richay/docker/radarr:/config
      - /mnt/media:/data
    depends_on:
      gluetun:
        condition: service_healthy
    restart: unless-stopped

  lidarr:
    image: lscr.io/linuxserver/lidarr:latest
    container_name: lidarr
    network_mode: service:gluetun
    environment:
      - PUID=${PUID:-1000}
      - PGID=${PGID:-1000}
      - TZ=${TZ:-Australia/Perth}
    volumes:
      - /home/richay/docker/lidarr:/config
      - /mnt/media:/data
    depends_on:
      gluetun:
        condition: service_healthy
    restart: unless-stopped


All five application containers share Gluetun’s network namespace. Because they are effectively living in the same network stack, they can also talk to each other over localhost.

For example:

qBittorrent from Sonarr/Radarr: http://127.0.0.1:8080
Prowlarr:                       http://127.0.0.1:9696
Sonarr:                         http://127.0.0.1:8989
Radarr:                         http://127.0.0.1:7878
Lidarr:                         http://127.0.0.1:8686


The ports are published on the Gluetun service because containers using network_mode: service:gluetun cannot publish their own ports.

Do not router-port-forward those WebUI ports. They’re management interfaces, not things you want flapping around on the public internet. If you want remote access, use a VPN/Tailscale and private DNS rather than raw WAN exposure.

If you want the same private hostname setup I use, see my Tailscale Split DNS guide.

4. Bring it up

cd /home/richay/docker-compose/media-vpn
docker compose up -d


Then check Gluetun first:

docker logs -f gluetun


Once it reports a healthy VPN connection, check the stack:

docker compose ps
docker exec gluetun wget -qO- https://ifconfig.me


The public IP shown from Gluetun should be the VPN exit IP, not your normal home WAN address.

5. qBittorrent login changed too

Current LinuxServer qBittorrent generates a temporary password for the admin user on startup. Grab it from the logs:

docker logs qbittorrent 2>&1 | grep -i password


Then log into:

http://DOCKER-HOST-IP:8080


and change the password.

About the torrent port

The old stack published TCP/UDP 6881 and it was easy to assume that meant qBittorrent had an externally forwarded VPN port.

It doesn’t.

ExpressVPN does not support port forwarding on its VPN servers. Publishing 6881 in Docker only exposes that port on the Docker host. It does not punch an inbound port through the ExpressVPN server.

qBittorrent will still download and seed through outbound connections, but unsolicited inbound peer connections through the VPN aren’t available. That can reduce peer connectivity compared with a VPN provider that offers torrent-friendly port forwarding.

Do Sonarr/Radarr/Lidarr really need the VPN?

Nope.

The stack above keeps everything behind Gluetun because it’s simple and matches the design of my old stack. But the important ones are generally:

  • qBittorrent: definitely the one whose traffic I want through the VPN.
  • Prowlarr: useful behind the VPN if your ISP blocks tracker/indexer sites.
  • Sonarr / Radarr / Lidarr: usually fine on the normal Docker network because they can talk to Prowlarr/qBittorrent locally.

If you want a cleaner split, move Sonarr/Radarr/Lidarr back onto a normal user-defined Docker network and leave only qBittorrent/Prowlarr sharing Gluetun. Slightly more networking to configure, slightly less “everything goes through the magic tunnel”. Pick your poison 🙂

What about polkaned/expressvpn?

It is not dead. I genuinely expected to find a dusty abandoned image here, but Docker Hub shows fresh 2026 builds and the current README supports ExpressVPN 5.x plus protocol selection including Lightway, OpenVPN and WireGuard.

A current minimal container still looks roughly like:

services:
  expressvpn:
    image: polkaned/expressvpn:latest
    container_name: expressvpn
    environment:
      - ACTIVATION_CODE=${EXPRESSVPN_ACTIVATION_CODE}
      - PROTOCOL=wireguard
    cap_add:
      - NET_ADMIN
    devices:
      - /dev/net/tun:/dev/net/tun
    privileged: true
    tty: true
    command: /bin/bash
    restart: unless-stopped


If you specifically want the real ExpressVPN client/protocols, that remains an option.

However, if other containers share that ExpressVPN container’s network namespace, follow the maintainer’s current DNS-sharing instructions. Their README explicitly warns that the dependent containers need the VPN-side resolv.conf handling to avoid DNS leakage.

That’s why I’m using Gluetun as the recommended fresh install: less janky plumbing, built-in firewall behaviour, and it was designed specifically for this sidecar/network-container use case.

Why Plex is no longer in this stack

The old article bundled Plex and get_iplayer into the same giant Compose file even though they weren’t using the VPN.

These days I keep unrelated services in separate stacks. It makes upgrades, troubleshooting and the inevitable “why the fuck did restarting my VPN also restart Plex?” moment much easier to avoid.

Plex should generally have its own stack/LXC and normal networking. It has absolutely no need to ride out through ExpressVPN just because qBittorrent does.

Old 2024 stack — historical note

HISTORICAL

The original stack used polkaned/expressvpn with qBittorrent, Prowlarr, Sonarr, Radarr and Lidarr all sharing the ExpressVPN network namespace. The architecture itself was valid, but the old example lacked the DNS-sharing requirement documented by the current image and used several now-stale image/environment conventions.

So I’m not pretending the original idea was wrong. It just needed its plumbing replaced before it flooded the carpet.

References

The nice bit is the original trick still survives: one VPN container, everything else borrows its network. The new version just has fewer opportunities to quietly leak DNS or make me wonder why I gave a VPN container the keys to the entire bloody kingdom 🙂

Docker Compose for Entertainment Stack

Status: CURRENT — MAJOR 2026 UPDATE
Last reviewed: 31 August 2026
Applies to: Docker Compose, Bazarr, Jellyfin, Seerr, Plex, Prowlarr, Radarr, Sonarr and Tautulli

The original idea behind this stack is still good: put related containers on one Docker network so they can find each other by service name instead of hard-coding IP addresses. A few of the actual applications and Docker habits from the old stack are now cactus though, so this is the cleaned-up version.

My entertainment stack has always been built around one simple Docker feature:

http://prowlarr:9696


No memorising container IP addresses. No changing configs when Docker hands a container a different IP. If two containers are on the same user-defined Docker network, Docker’s internal DNS lets them talk to each other using the service/container name.

That part of the original article was spot on and is still how I’d do it today.

What’s changed since the old stack?

  • Overseerr is gone. The original project was archived in February 2026. Overseerr and Jellyseerr have effectively converged into Seerr, which is the current maintained project.
  • Watchtower is gone. The upstream project was archived in December 2025 and now explicitly says it is no longer maintained.
  • The top-level Compose version: "3.6" line is obsolete and ignored by modern Docker Compose.
  • I’ve changed application configs from anonymous/named Docker volumes to obvious bind mounts under /home/richay/docker/. Much easier to back up and inspect when something inevitably goes sideways at 1am.
  • Radarr/Sonarr/Bazarr now see one consistent /data tree instead of three completely different host paths.
  • Prowlarr and Seerr don’t need access to your entire media library, so they no longer get it. Less access, less bullshit.
  • Plex still uses host networking in this example because LinuxServer continues to document that as its standard setup, but its old ports: entry has been removed because Docker ignores published ports in host-network mode.

Overseerr → Seerr

The old stack used:

sctx/overseerr:latest


That repository was archived on 15 February 2026. The current maintained project is Seerr, which supports Plex, Jellyfin and Emby and still integrates with Sonarr and Radarr.

The current official Docker image is:

ghcr.io/seerr-team/seerr:latest


If you’re migrating an existing Overseerr/Jellyseerr database rather than starting fresh, use Seerr’s official migration guide. Don’t just point a random new image at the old database and hope Docker Jesus sorts it out 🙂

Watchtower has been removed

The old stack let Watchtower automatically pull and replace containers. The Watchtower maintainers archived the project on 17 December 2025 and now state that it is no longer maintained.

I don’t think unattended auto-updates are worth handing permanent Docker-socket access to an abandoned container.

Updating this stack manually is hardly an ordeal:

docker compose pull
docker compose up -d
docker image prune


LinuxServer currently recommends Diun if you want notifications that new images are available, rather than automatically updating everything while you’re asleep and waking up to seven broken services and a strong urge to throw the server into the pool.

Folder layout

I keep Compose files and persistent Docker data separate:

/home/richay/docker-compose/   # Compose files and small hand-managed config
/home/richay/docker/           # Persistent container data


A simple media tree might look like:

/mnt/media/
├── downloads/
└── media/
    ├── movies/
    ├── tv/
    └── music/


The important part is that Radarr/Sonarr and your download client see the same filesystem through the same /data container path. That allows hardlinks and atomic moves instead of copying a massive file from one mount to another and then deleting the original.

Create the config folders:

mkdir -p /home/richay/docker-compose/entertainment
mkdir -p /home/richay/docker/{bazarr,jellyfin,seerr,plex,prowlarr,radarr,sonarr,tautulli}
mkdir -p /mnt/media/{downloads,media/movies,media/tv,media/music}


Current entertainment Compose stack

This keeps the spirit of my original stack without carrying all the old baggage:

services:
  bazarr:
    image: lscr.io/linuxserver/bazarr:latest
    container_name: bazarr
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
    volumes:
      - /home/richay/docker/bazarr:/config
      - /mnt/media:/data
    ports:
      - "6767:6767"
    restart: unless-stopped
    networks:
      - entertainment

  jellyfin:
    image: lscr.io/linuxserver/jellyfin:latest
    container_name: jellyfin
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
    volumes:
      - /home/richay/docker/jellyfin:/config
      - /mnt/media/media:/data/media:ro
    ports:
      - "8096:8096"
      # Optional local discovery:
      # - "7359:7359/udp"
      # Optional DLNA/service discovery:
      # - "1900:1900/udp"
    # Intel/AMD hardware acceleration:
    # devices:
    #   - /dev/dri:/dev/dri
    restart: unless-stopped
    networks:
      - entertainment

  seerr:
    image: ghcr.io/seerr-team/seerr:latest
    container_name: seerr
    init: true
    environment:
      - LOG_LEVEL=info
      - TZ=Australia/Perth
      - PORT=5055
    volumes:
      - /home/richay/docker/seerr:/app/config
    ports:
      - "5055:5055"
    healthcheck:
      test: wget --no-verbose --tries=1 --spider http://localhost:5055/api/v1/settings/public || exit 1
      start_period: 20s
      timeout: 3s
      interval: 15s
      retries: 3
    restart: unless-stopped
    networks:
      - entertainment

  plex:
    image: lscr.io/linuxserver/plex:latest
    container_name: plex
    network_mode: host
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
      - VERSION=docker
      - PLEX_CLAIM=
    volumes:
      - /home/richay/docker/plex:/config
      - /mnt/media/media:/data/media:ro
    # Intel/AMD hardware acceleration:
    # devices:
    #   - /dev/dri:/dev/dri
    restart: unless-stopped

  prowlarr:
    image: lscr.io/linuxserver/prowlarr:latest
    container_name: prowlarr
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
    volumes:
      - /home/richay/docker/prowlarr:/config
    ports:
      - "9696:9696"
    restart: unless-stopped
    networks:
      - entertainment

  radarr:
    image: lscr.io/linuxserver/radarr:latest
    container_name: radarr
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
    volumes:
      - /home/richay/docker/radarr:/config
      - /mnt/media:/data
    ports:
      - "7878:7878"
    restart: unless-stopped
    networks:
      - entertainment

  sonarr:
    image: lscr.io/linuxserver/sonarr:latest
    container_name: sonarr
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
    volumes:
      - /home/richay/docker/sonarr:/config
      - /mnt/media:/data
    ports:
      - "8989:8989"
    restart: unless-stopped
    networks:
      - entertainment

  tautulli:
    image: lscr.io/linuxserver/tautulli:latest
    container_name: tautulli
    environment:
      - PUID=1000
      - PGID=1000
      - TZ=Australia/Perth
    volumes:
      - /home/richay/docker/tautulli:/config
    ports:
      - "8181:8181"
    restart: unless-stopped
    networks:
      - entertainment

networks:
  entertainment:
    name: entertainment


Why keep an explicit entertainment network?

Docker Compose automatically creates a default network and provides service-name DNS anyway, so technically the explicit network isn’t required if everything lives in this one Compose project.

I still like naming it entertainment because it gives me a stable network name that another stack can deliberately join later.

For example, Radarr can talk to Sonarr/Prowlarr-style services using names such as:

http://prowlarr:9696
http://radarr:7878
http://sonarr:8989
http://seerr:5055
http://jellyfin:8096


No container IPs required. Docker handles the internal DNS. Fucking lovely.

Plex is the odd bastard

Plex uses network_mode: host in the LinuxServer recommended configuration, so it does not join the entertainment bridge network in this example.

That also means this old combination was pointless:

network_mode: host
ports:
  - 32400:32400


Docker explicitly ignores published ports when host networking is enabled because Plex is already binding directly to the host’s network stack.

So Tautulli/Seerr should reach Plex using the Docker host’s LAN address, for example:

http://192.168.1.10:32400


Replace that with your actual Docker/Plex host address.

Jellyfin ports

The only Jellyfin port I expose by default in the stack is:

8096/tcp  # normal Jellyfin HTTP web/API


LinuxServer still documents 8920/tcp, 7359/udp and 1900/udp as optional ports. I don’t bother with Jellyfin’s own HTTPS port 8920 when Traefik is handling TLS in front of it.

7359/udp is useful for local client discovery and 1900/udp is used for service/DLNA discovery. Uncomment them only if you actually use those features.

Hardware transcoding

For Intel/AMD hardware acceleration, LinuxServer’s Jellyfin image still supports mapping the host’s DRI device:

devices:
  - /dev/dri:/dev/dri


The same mapping can be used for Plex when the Docker host has the GPU available.

If you’re running Docker inside a Proxmox LXC, get the GPU working in the LXC first. Then pass it to Docker. Debugging Proxmox → LXC → Docker → Jellyfin all at once is how hobbies turn into drinking problems 🙂

Where’s qBittorrent?

I deliberately left the download client out of this stack.

If qBittorrent needs to live behind a VPN, I prefer it in a dedicated VPN/download stack rather than mixing VPN networking into Plex, Jellyfin and everything else.

See my updated Docker Stack with ExpressVPN article for the VPN side.

Radarr and Sonarr can still use that qBittorrent instance as their download client — it does not need to be in the same Compose file.

Don’t mount everything into everything

My old stack gave Prowlarr and Overseerr access to media, storage and downloads even though they had no bloody reason to touch those files.

The new split is:

  • Radarr / Sonarr / Bazarr: access to the shared /data tree.
  • Plex / Jellyfin: read-only access to /data/media.
  • Prowlarr / Seerr / Tautulli: config only; no media filesystem access required.

It’s cleaner and reduces the blast radius if one container ever gets compromised.

Starting and checking the stack

cd /home/richay/docker-compose/entertainment
docker compose up -d
docker compose ps


Then confirm the internal Docker DNS works from one of the containers:

docker exec sonarr getent hosts prowlarr
docker exec sonarr getent hosts radarr


If those return container IPs, the service-name networking is doing exactly what we wanted.

Old stack — what I’d keep and what I’d bin

  • Keep: one shared Docker network and service-name communication.
  • Keep: LinuxServer images for the *arr apps, Jellyfin, Plex and Tautulli.
  • Keep: Perth timezone and sensible PUID/PGID ownership.
  • 🛠️ Change: Overseerr → Seerr.
  • 🛠️ Change: named volumes → obvious bind-mounted config folders.
  • 🛠️ Change: multiple inconsistent media paths → one /data tree.
  • 🗑️ Bin: obsolete Compose version: "3.6".
  • 🗑️ Bin: Watchtower.
  • 🗑️ Bin: pointless Plex ports: while using host networking.

References

The original stack wasn’t bad at all — the networking idea aged really well. It just accumulated a couple of dead projects, redundant mounts and Docker archaeology around it. A bit of a clean-out and she’s good again 🙂

Plex settings in web app (Subtitles, Audio)

Status: CURRENT
Last reviewed: 31 August 2026
Applies to: Plex Web App

This is deliberately a simple one. Dad Help #1 does not need to become a 4,000-word enterprise authentication whitepaper 😅.

Dad Help #1

Using the web version of Plex at app.plex.tv, my Dad wasn’t sure how to change the audio track or turn subtitles on and off.

Hopefully this helps someone else’s Dad too 😉

While the movie is playing

Move the mouse over the video so the Plex playback bar appears.

Click the Settings button in the playback controls.

Plex Web App playback controls showing the Settings button

From there you can change things such as:

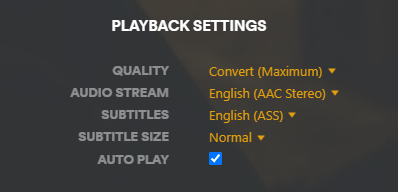
  • Audio Stream — choose another available audio track.
  • Subtitles — turn subtitles off or select an available subtitle track.
  • Subtitle Size — change how large the subtitles appear.
  • Quality — change playback quality if needed.
Plex Web App playback settings showing audio and subtitle options

Once you’re finished, click the Settings button again or click back on the movie to close the options.

That’s it. No server settings, no transcoder witchcraft, no Docker bullshit. Just subtitles for Dad 😀

You can also change them before pressing Play

Plex also lets you choose the audio and subtitle track from the movie or episode details page before playback starts.

If more than one track is available, use the dropdown next to Audio or Subtitle and choose the one you want.

Want Plex to choose automatically?

If Dad keeps having to change the same thing every movie, Plex also has account-level audio and subtitle preferences.

In Plex Web go to your user menu in the top-right, choose Account Settings, then find Audio & Subtitle Settings.

There you can set a preferred audio language, preferred subtitle language and when subtitles should appear automatically.

Worth setting once if the answer is always “English audio, subtitles only when people start speaking Klingon” 🙂

References

Portainer: Deleting a Broken Stack Throwing Errors on Linux

Status: CURRENT — RECOVERY WORKAROUND
Last reviewed: 31 August 2026
Applies to: Portainer CE/BE on Docker Standalone when a stack exists in Portainer but its stored Compose file is missing

This is still a real Portainer failure mode. Recent Portainer issues show stacks can become undeletable when the stored /data/compose/<stack-id> directory or Compose file disappears. This workaround recreates the minimum Portainer expects so the stack can be deleted normally.

Every now and again Portainer manages to get itself into a stupid state where a stack still exists in its database, but the Compose file behind it has disappeared.

You then try to delete the broken stack and Portainer throws something along the lines of:

could not get the contents of the file 'docker-compose.yml'

or

open /data/compose/234/docker-compose.yml:
no such file or directory


Excellent. The stack is broken because the file is missing, and Portainer refuses to delete the broken stack because the file is missing. Very helpful 😂.

Is this still relevant?

Yep.

This bug has been reported in Portainer for years, and there are still current examples. A July 2026 Portainer issue describes a failed Git Pull and redeploy operation leaving the stack’s /data/compose/<id> directory without the Compose file, after which the stack cannot be edited or redeployed normally.

Older reports describe the same basic workaround as this article: recreate the missing directory/file, then let Portainer perform the deletion itself.

Important: we’re touching Portainer’s persistent /data directory directly. Don’t start randomly deleting folders in there because some bloke on the internet — including me — said so. Back up Portainer first 🙂

1. Find the stack ID

The easiest clue is normally the error itself. Portainer may show a path such as:

/data/compose/234/docker-compose.yml


In that example the stack ID is:

234


You may also be able to see the stack ID in the Portainer URL when viewing the stack.

2. Find where Portainer’s /data actually lives

My old article assumed Portainer used the default named volume at:

/var/lib/docker/volumes/portainer_data/_data


That’s common, but it is not guaranteed. Portainer might be using a different named volume or a bind mount.

Ask Docker where the Portainer container’s /data mount actually points:

docker inspect portainer   --format '{{range .Mounts}}{{if eq .Destination "/data"}}{{.Source}}{{end}}{{end}}'


For a standard named volume that may return:

/var/lib/docker/volumes/portainer_data/_data


If your Portainer container isn’t actually called portainer, find it first:

docker ps --format 'table {{.Names}}\t{{.Image}}' | grep -i portainer


3. Back up Portainer before poking it

Set the returned path as a variable:

PORTAINER_DATA="$(docker inspect portainer   --format '{{range .Mounts}}{{if eq .Destination "/data"}}{{.Source}}{{end}}{{end}}')"

echo "$PORTAINER_DATA" 


Make sure that printed the correct Portainer data directory before continuing.

Then take a quick filesystem backup:

sudo tar -czf "/root/portainer-data-backup-$(date +%Y%m%d-%H%M%S).tar.gz"   -C "$PORTAINER_DATA" .


For a tiny recovery job this takes bugger-all effort and gives you an escape hatch if your fingers become enthusiastic.

4. Check the Compose storage

List Portainer’s stored stack directories:

sudo ls -lah "$PORTAINER_DATA/compose/" 


If your broken stack is ID 234, check it directly:

sudo ls -lah "$PORTAINER_DATA/compose/234/" 


You will normally find one of two things:

  • The entire 234 directory is missing.
  • The directory exists but docker-compose.yml is missing.

5. Recreate only what Portainer is complaining about

If the whole stack directory is missing:

sudo mkdir -p "$PORTAINER_DATA/compose/234" 


Now create the missing Compose file:

sudo nano "$PORTAINER_DATA/compose/234/docker-compose.yml" 


It does not need to recreate your entire original stack if your only goal is to get rid of the dead Portainer record.

I put a single YAML comment in it:

# recovery placeholder so Portainer can delete the broken stack


Save the file.

You can do the same thing without opening an editor:

echo '# recovery placeholder so Portainer can delete the broken stack' |   sudo tee "$PORTAINER_DATA/compose/234/docker-compose.yml" >/dev/null


6. Try deleting the stack again

Go back to:

Portainer → Stacks → broken stack → Delete this stack


If the missing Compose file was the blocker, Portainer should now be able to finish deleting the stale stack record.

That’s it. We essentially gave Portainer the world’s saddest Compose file so it would finally agree to clean up its own mess 😀

What if it complains about stack.env instead?

Another reported version of this bug complains about:

failed to create env file:
open /data/compose/234/stack.env:
no such file or directory


In that case, recreating the missing stack directory may be enough because Portainer can then create stack.env itself.

If the error specifically says a required file is missing, follow the error rather than blindly manufacturing a dozen random files.

Git-backed stacks are a bit different

If the stack originally came from Git, first consider whether restoring the Compose file/repository path is the cleaner fix.

Portainer’s current Git stack handling still expects the configured Compose path to exist. Renaming/removing that file can leave Portainer unable to redeploy or delete the stack cleanly.

If you only want the stale Portainer entry gone and the Git source is already toast, the placeholder-file recovery above is still useful.

What I would NOT do

  • Don’t delete the entire portainer_data volume. That’s the nuclear option and wipes Portainer’s persistent state.
  • Don’t start editing Portainer’s database manually just to remove one broken stack unless you absolutely know what you’re doing.
  • Don’t delete random numbered directories from /data/compose.
  • Don’t assume the stack ID is the same thing as a Docker container ID.

The goal here is deliberately boring: identify the exact missing stack directory, recreate the minimum expected file, let Portainer delete it normally, fuck off and do something more interesting.

Old command from the original article

The original guide started with:

sudo ls /var/lib/docker/volumes/portainer_data/_data/compose/


That is still correct if Portainer uses a Docker named volume called portainer_data. The current article simply discovers the mount first so the same fix also works with custom volumes and bind mounts.

References

A very small fix for a very annoying circular error. Portainer: “I can’t delete the stack because the file doesn’t exist.” Me: “Fine, here’s a fucking comment file.” Portainer: “Oh okay then.” 🙂